4 November 2026·5 min read
Running Claude Code and Codex headless, so another agent can hand them work
A coding agent is a command-line program, which means anything that can run a program can run one. The flags are the easy part — the part worth getting right is what it is allowed to touch and what it reports back.
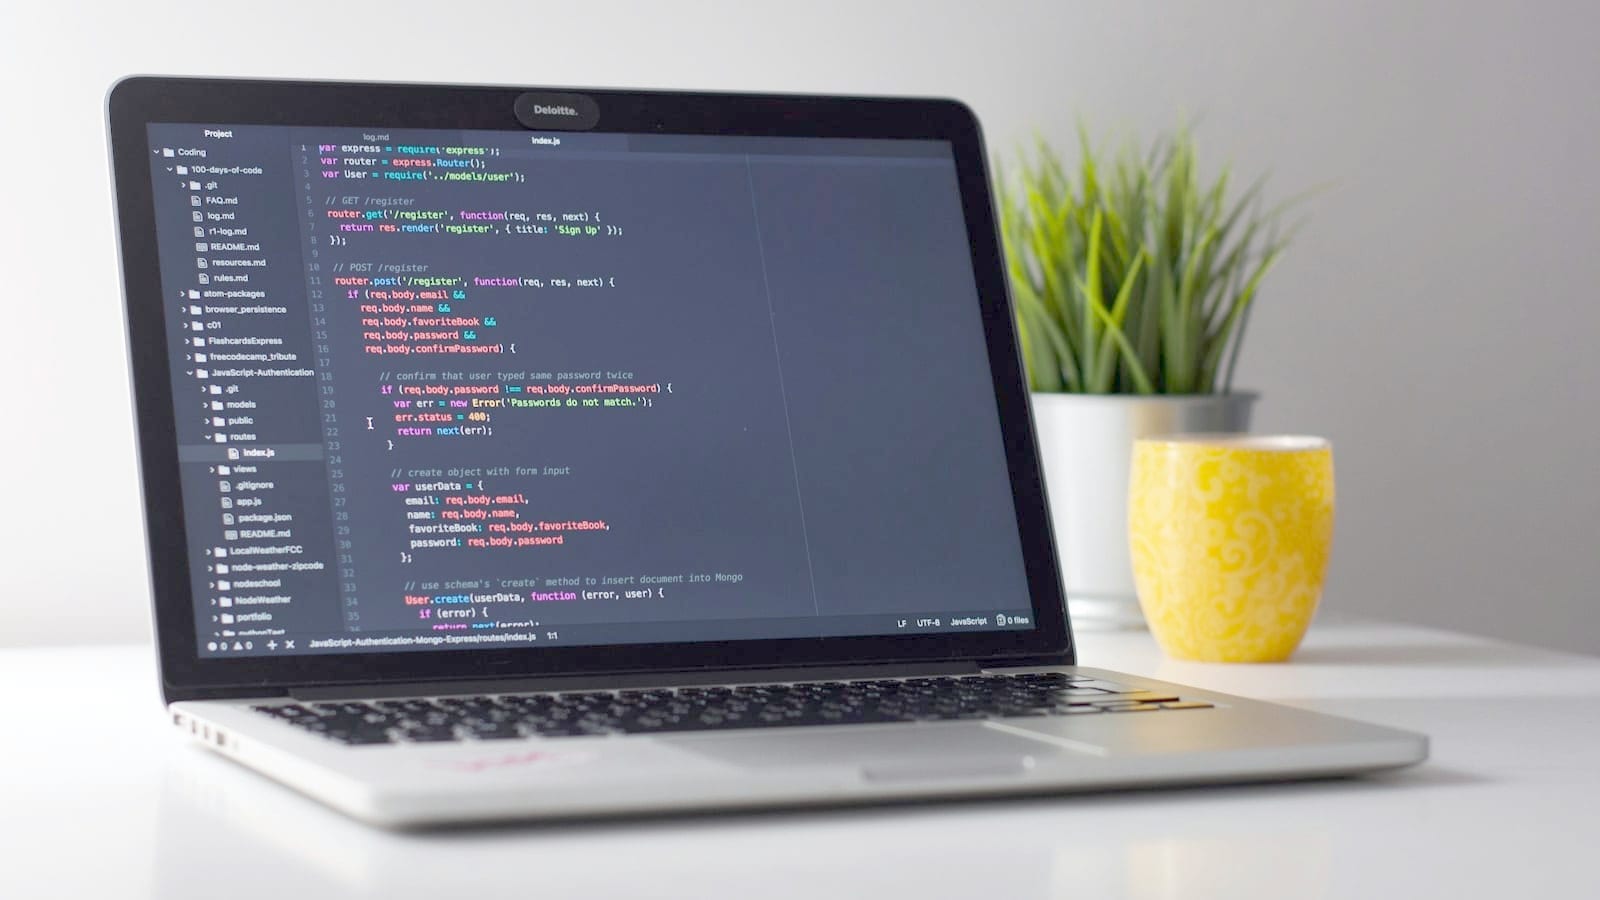
Most people meet a coding agent as a thing you talk to in a terminal. That is one mode, and it is not the interesting one. Claude Code and Codex are both ordinary command-line programs, which means anything that can run a program can run them — a cron job, a CI step, a webhook handler, or another agent that has a computer of its own and no idea how to write the code it has just been asked for.
That last case is the one people are building towards at the moment: a chat agent that is good at talking to you, which delegates the actual engineering to a coding agent and reports back what happened. The pattern is worth understanding on its own terms, because the delegation — not the model — is where it goes wrong.
Headless is one flag
Both CLIs have a non-interactive mode. Claude Code takes the prompt as an argument and prints the result: claude -p "the task", with --model to pin which model runs it. Codex has a subcommand for the same thing: codex exec, with -m for the model. Neither opens a session, neither waits for input, and both exit with a status code, which is what makes them callable from something that is not a human.
Model names are the first thing to break. They change with the plan you are on, so a name hard-coded into whatever is calling the CLI will one day be rejected by an account that is perfectly healthy. Keep it in one place you can change.
Give it the smallest set of permissions the job needs
This is the part that gets skipped, and it is the part that matters. An agent invoked with everything enabled will happily do everything — including the destructive thing it inferred from an ambiguous instruction. Both CLIs let you narrow it, and both default to narrower than most people assume.
- Claude Code: --allowedTools, listing only what this specific task needs. A task that reads and greps does not need a shell.
- Codex: --sandbox, set to the least access the task can succeed with — read-only where that is enough, workspace-write where it has to edit.
- Both: a working directory stated explicitly. An agent given no boundary treats the whole machine as the project.
The instinct is to grant everything so the run does not fail halfway. Resist it. A run that stops and says it was not allowed to do something is cheap. A run that was allowed to do something nobody asked for is not.
The report back is the product
When a person runs an agent, they watch it. When a program runs one, nobody does — so the only thing anyone will ever see is whatever it says at the end. A runner that answers "done" is useless. The three things worth insisting on are what ran, what changed, and what failed, with failures stated rather than smoothed over.
I learnt that one the hard way on this site rather than in a chain of agents: a deploy script with its output sent to /dev/null failed its build, reported nothing, reloaded anyway, and the site went down. Suppressed output is the same bug whether the thing being silenced is a build or an agent.
An agent you cannot see is only as good as the account it gives of itself.
One computer, many callers
The usual setup gives the runner a machine and lets everything else share it. That is cheap and it is convenient, and it has a consequence worth saying out loud: every caller on that machine inherits every account signed in on it. Your Claude session, your ChatGPT session, whatever else happens to be logged in. They also share your plan limits, so a runaway loop in one caller is a bill or a lockout for all of them.
Isolation per caller is the fix, and it is the same argument I ended up making for Agent Browser — every project and every coding agent gets its own port and its own profile, so two of them working at once cannot collide or read each other’s session. Give a shared runner dummy work first, and watch what it touches, before you give it anything real.
When this is worth doing
It earns its keep when the work is well-specified and repetitive: a migration across many files, a scripted review, a fix applied to twenty repositories. It is a poor fit when the task needs judgement about what to build, because the thing calling the agent cannot supply that judgement and will confidently invent it instead.
The honest state of it: the headless invocation is solid and I use it daily. Chains of agents handing work to each other are newer, and most published setups — mine included — have proved the runner works far more thoroughly than they have proved the handoff does. Treat that as the experimental half.
Isolation, builtA macOS browser every project and coding agent drives on its own isolated port, so parallel work never collides.↗The Grok Bot version of this, by Anish SinghThe step-by-step for wiring these runners into Grok Bot specifically, with the runner prompts — the setup that prompted this piece. His method follows a video by Clearmud.↗What AI automation actually meansThe quieter version that removes real work.↗